If you’re not able to prove that the system consistently meets whatever business threshold you’re willing to set, then you really can’t afford to deploy it.
 Simon WilsonLead GenAI Data Science @ Telstra
AI agents are becoming easier to build, yet most companies can’t explain why they fail. That uncertainty makes it risky to place them in customer-facing or transactional workflows, where one wrong source, decision, or system action can directly affect customers. CX leaders need to test how an agent works to know how it chooses information, makes decisions, and responds when conditions change.
Simon Wilson, Lead GenAI Data Science at Telstra, leads multidisciplinary teams developing and deploying generative AI applications. His background in marketing, commercial retail management, and leading machine learning teams shapes his focus on proving that AI systems are reliable enough for real business use.
“The increasing ease with which you can build AI agents is probably what makes them so dangerous,” Wilson says. A few convincing answers can encourage teams to launch a system before they understand its failures. His team’s work shows how realistic test questions, detailed error analysis, and repeated evaluation give CX leaders stronger evidence for deployment decisions.
Realistic questions as the foundation for evaluation
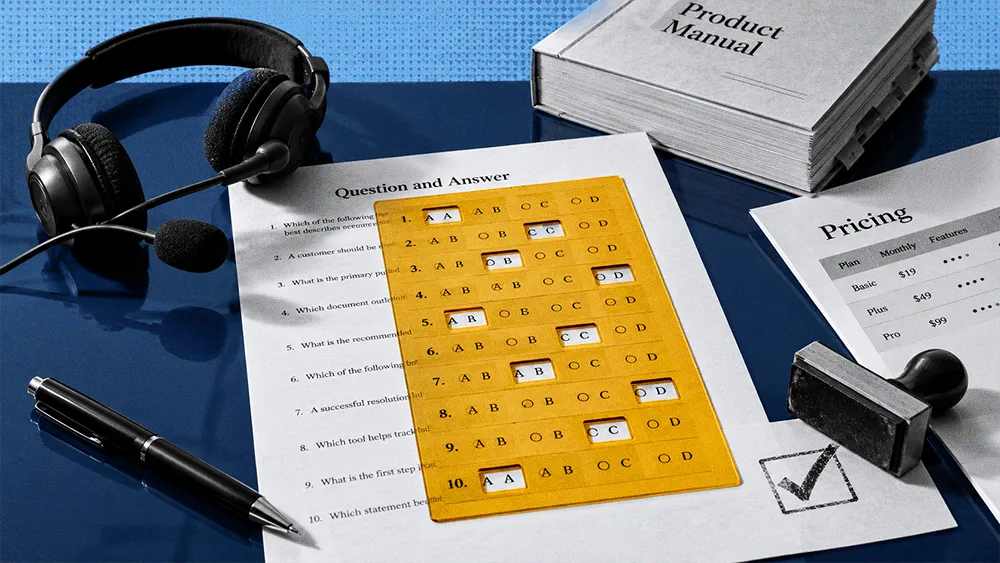
Wilson’s “golden test set” pairs realistic questions with validated answers and supporting documents. Asking subject matter experts to write 100 questions, answers, and source references from scratch proved slow, so developers generated examples from manuals and pricing pages with a large language model. The first results sounded like exam questions. “The question might be correct, and the answer might be correct, but it’s not a question a customer service agent would ever ask,” Wilson says.
Refining the prompts made the questions more realistic, while experts checked the results. “Then we would give, say, 500 generated questions and answers to our SMEs and ask them to validate them,” he explains. The approved answers became the benchmark for testing the chatbot.
Effective AI evaluation looks beyond the final answer
Diagnosing failures in Wilson’s RAG chatbots required more than an accuracy score. When an answer failed, an engineer might have to search through system records and unfamiliar documents to find the cause. The manual review took time because the engineers weren’t subject matter experts in the material.
“You have to look at all the traces and logs and work out where it went wrong,” he says. His group tracked 14 metrics to distinguish incorrect document selection, wrong passages, and invented information. “Once you can see where it’s going wrong, you can give that information to the engineering team and point them directly toward specific issues to fix,” Wilson explains.
The same evaluation challenge becomes even more complex with agents that take actions. An agent changing a customer’s address needs the correct input, interpretation, decision, and action, including the right connection to the right system. Each stage creates another point where something can go wrong and needs to be investigated.
Repeated testing turns targeted fixes into accuracy gains
A small change to an AI’s instructions can fix one problem and cause another. Wilson’s team tested each change to check both. “You’re checking two things: did I fix what I was trying to fix, and did I break anything else?” he says. Doing this manually took days. The team ran questions through the system, reviewed wrong answers, looked for patterns, and suggested changes to engineers.
Automation cut that process to minutes. LLMs compared the system’s responses with validated answers and explained their assessments. Another model summarized the findings for engineers. The team could test 500 or 1,000 questions, produce reports, and run several rounds of testing each day.
Wilson says the team later achieved over 90% accuracy on a RAG chatbot built for a different task they hadn’t worked on before. He credits that result to making focused changes and testing them repeatedly.
Agent evaluation reveals the risks accuracy scores miss
Wilson references the Princeton research paper Towards a Science of AI Agent Reliability, which identifies agent evaluation through four dimensions: Consistency, Robustness, Predictability, and Safety.
Consistency means checking whether repeated evaluations produce steady results. Robustness means knowing how changes in conditions affect performance, including whether performance deteriorates in a way teams can detect. Predictability concerns knowing where failures are likely, while safety requires understanding how far their consequences could spread.
These checks matter even more when an agent can change records or take actions across several systems. Before seeking approval to launch, developers need evidence of how the system could fail and what those failures could affect. An accuracy score alone can’t answer those questions. “If you’re not able to prove that the system consistently meets whatever business threshold you’re willing to set, then you really can’t afford to deploy it,” Wilson says.
Business expertise shapes the standard for AI performance
Engineers can’t evaluate AI agents alone. They need business experts who can identify trusted documents, explain unclear cases, and check whether the system understood the information correctly. Wilson requires at least two subject matter experts to join each project. During development, they may work with the engineering team two or three days a week. “It needs to be a joint team and a joint production,” he says.
Business experts also help set the accuracy target. Wilson first asks how well the current process performs and what could happen if it fails. The right target depends on the task and the harm an error could cause. A high average score isn’t enough if the remaining errors create serious risks.
As agents become easier to build, the harder judgment is deciding when to put them to work. Evaluation gives CX leaders a basis for that decision by showing which problems have been resolved and where limitations remain. “You also have confidence that, having tested it multiple times, you understand the reliability of that system,” Wilson concludes.